Interview Cake
Topological sort is an algorithm that takes a directed graph and returns an array of its nodes where every node appears before all the nodes it points to. An ordering like that only exists if the graph has no cycles (it's a directed acyclic graph, or DAG). The two standard ways to find one—Kahn's algorithm and depth-first search—both run in O(V + E) time.
The ordering of the nodes in the array is called a topological ordering.
| Kahn's algorithm (BFS) | DFS-based | |
|---|---|---|
| time | O(V + E) | O(V + E) |
| space | O(V) | O(V) |
| detects cycles? | Yes—some nodes never get down to zero incoming edges | Yes—the search runs into a node that's still on its current path |
(V is the number of nodes, or vertices, and E is the number of edges.)
Here's an example:
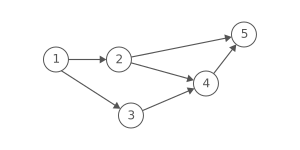
Since node 1 points to nodes 2 and 3, node 1 appears before them in the ordering. And, since nodes 2 and 3 both point to node 4, they appear before it in the ordering.
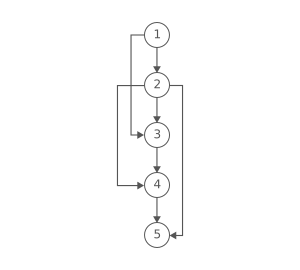
So [1, 2, 3, 4, 5] would be a topological ordering of the graph.
Can a graph have more than one valid topological ordering? Yep! In the example above, [1, 3, 2, 4, 5] works too.
Cyclic Graphs
Look at this directed graph with a cycle:
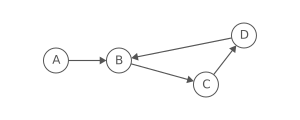
The cycle creates an impossible set of constraints—B has to be before and after D in the ordering.
As a rule, cyclic graphs don't have valid topological orderings. That makes topological sort a handy way to detect cycles, too: both of the algorithms below notice when they run into one.
What about undirected graphs? An undirected edge goes both ways, so its two nodes would each have to come before the other. Topological sort only makes sense for directed graphs.
Kahn's Algorithm
How can we produce a topological ordering for this directed graph?
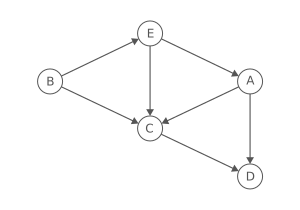
Well, let's focus on the first node in the topological ordering. That node can't have any incoming directed edges; it must have an indegree of zero.
Why?
Because if it had incoming directed edges, then the nodes pointing to it would have to come first.
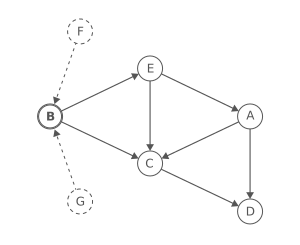
So, we'll find a node with an indegree of zero and add it to the topological ordering.
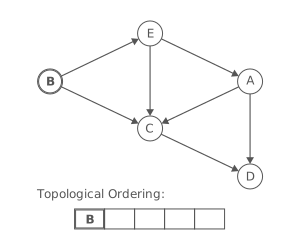
That covers the first node in our topological ordering. What about the next one?
Once a node is added to the topological ordering, we can take the node, and its outgoing edges, out of the graph.
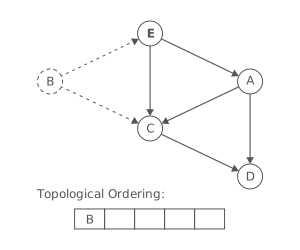
Then, we can repeat our earlier approach: look for any node with an indegree of zero and add it to the ordering.
This is a common algorithm design pattern:
- Figure out how to get the first thing.
- Remove the first thing from the problem.
- Repeat.
Here's what this looks like on our graph. We'll grab a node with an indegree of 0, add it to our topological ordering and remove it from the graph:
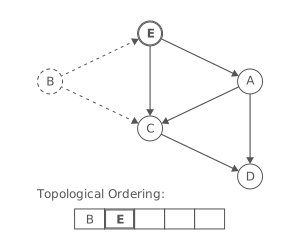
and repeat
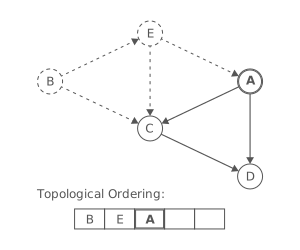
and repeat
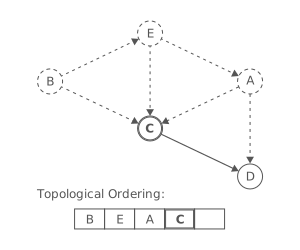
until we're
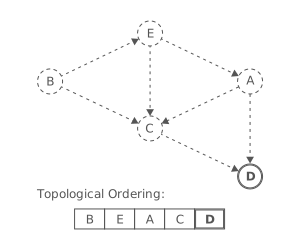
out of nodes.
This approach is called Kahn's algorithm, after A. B. Kahn, who described it in 1962. It's sometimes called the "BFS" approach to topological sort, because it works outward from the nodes with no prerequisites, a bit like a breadth-first search.
Step by step
Here's that same run as a table. Our graph's edges are B→C, B→E, C→D, E→A, E→C, A→C, and A→D, so the starting indegrees are A: 1, B: 0, C: 3, D: 2, and E: 1.
| Step | Node with indegree 0 | Indegree updates | Topological ordering so far |
|---|---|---|---|
| 1 | B | C: 3 → 2, E: 1 → 0 | B |
| 2 | E | A: 1 → 0, C: 2 → 1 | B, E |
| 3 | A | C: 1 → 0, D: 2 → 1 | B, E, A |
| 4 | C | D: 1 → 0 | B, E, A, C |
| 5 | D | (no outgoing edges) | B, E, A, C, D |
Notice that at every step, exactly one node had an indegree of zero, so we never had a choice to make. That means B, E, A, C, D is the only valid topological ordering for this graph. In general, a topological ordering is unique exactly when every pair of neighbors in the ordering is connected by an edge (here: B→E, E→A, A→C, and C→D).
Implementing Kahn's Algorithm
We'll use the strategy we outlined above:
- Identify a node with no incoming edges.
- Add that node to the ordering.
- Remove it from the graph.
- Repeat.
We'll keep looping until there aren't any more nodes with indegree zero. This could happen for two reasons:
- There are no nodes left. We've taken all of them out of the graph and added them to the topological ordering.
- There are some nodes left, but they all have incoming edges. This means the graph has a cycle, and no topological ordering exists.
One small tweak. Instead of actually removing the nodes from the graph (and destroying our input!), we'll use a hash map to track each node's indegree. When we add a node to the topological ordering, we'll decrement the indegree of that node's neighbors, representing that those nodes have one fewer incoming edges.
Any node with an indegree of zero is safe to take next, so it doesn't matter whether we hold those nodes in a queue or a stack. Different choices can just produce different (equally valid) orderings.
Let's code it up!
Topological Sort Using DFS
There's a second classic approach, built on depth-first search.
Here's the key insight. In a DFS, we don't finish a node until we've finished every node we can reach from it. So by the time a node finishes, every node that has to come after it in the ordering has already finished.
That means if we write down the nodes in the order they finish, we get a topological ordering backwards. Reverse it, and we're done.
To catch cycles, we'll keep track of one of three states for each node:
- Unvisited: we haven't reached it yet.
- Visiting: it's on our current DFS path. We've started exploring from it, but we haven't finished.
- Visited: we've finished it, along with everything reachable from it.
If our search ever reaches a node that's still visiting, we've followed edges in a loop back onto our own path. That's a cycle, so no topological ordering exists.
Why do we need two "seen" states instead of one? Running into a visited node is totally fine—it just means two paths lead to the same place (like B→C and B→E→C in our example). Only a node that's still visiting means we've looped back on ourselves.
Since this version is recursive, the call stack can get as deep as the longest path in the graph—up to V calls. On really big graphs that can cause a stack overflow, so Kahn's algorithm (or a DFS that uses an explicit stack) is the safer choice there.
Time and Space Complexity
Breaking Kahn's algorithm into chunks, we:
- Determine the indegree for each node. We start every node's count at zero and then look at each directed edge once, so this is O(V + E) time (where V is the number of nodes and E is the number of edges).
- Find nodes with no incoming edges. This is a simple loop through all the nodes with some number of constant-time appends. O(V) time.
- Add nodes until we run out of nodes with no incoming edges. This loop could run once for every node—O(V) times. In the body, we:
- Do two constant-time operations on an array to add a node to the topological ordering.
- Decrement the indegree for each neighbor of the node we added. Over the entire algorithm, we'll end up doing exactly one decrement for each edge, making this step O(E) time overall.
- Check if we included all nodes or found a cycle. This is a fast O(1) comparison.
All together, the time complexity is O(V + E).
That's the fastest time we can expect, since we'll have to look at all the nodes and edges at least once.
What about space complexity? Here are the data structures we created:
- indegrees—this has one entry for each node in the graph, so it's O(V) space.
- nodesWithNoIncomingEdges—in a graph with no edges, this would start out containing every node, so it's O(V) space in the worst case.
- topologicalOrdering—in a graph with no cycles, this will eventually have every node. O(V) space.
All in all, we have three structures and they're all O(V) space. Overall space complexity: O(V).
This is the best space complexity we can expect, since we must allocate a return array which costs O(V) space itself.
What about the DFS version?
It's also O(V + E) time. Each node goes from unvisited to visiting to visited exactly once, and we only loop through a node's neighbors the first time we visit it, so we follow each edge once. Reversing the finished nodes at the end is another O(V).
And it's O(V) space: the node states, the list of finished nodes, and the call stack (up to V calls deep) are each O(V).
Kahn's Algorithm vs. DFS: Which Should You Use?
Both run in O(V + E) time and O(V) space, and both detect cycles. The differences are practical:
| Kahn's algorithm | DFS-based | |
|---|---|---|
| Main idea | Repeatedly take a node with no remaining incoming edges | Record nodes as their DFS finishes, then reverse that order |
| Data structures | Indegree counts, plus a queue (or stack) of nodes that are ready | Node states, plus recursion (or an explicit stack) |
| Cycle check | The ordering ends up with fewer nodes than the graph | The search reaches a node that's still "visiting" |
| Recursion | None, so no risk of a stack overflow | The recursive version can overflow the stack on very deep graphs |
| Handy extras | Processes nodes in "waves," which helps with scheduling questions. Swap the queue for a priority queue to get the alphabetically smallest ordering. | Easy to bolt onto a DFS you're already writing |
In a coding interview, either one is a great answer. Kahn's algorithm is a good default, since it's iterative and its cycle check is just a count.
Uses
The most common use for topological sort is ordering steps of a process where some of the steps depend on each other.
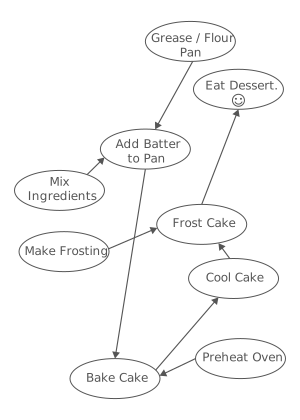
As an example, when making chocolate bundt cake,
- The ingredients have to be mixed before going in the bundt pan.
- The bundt pan has to be greased and floured before the batter can be poured in.
- The oven has to be preheated before the cake can bake.
- The cake has to be baked before it cools.
- The cake has to cool before it can be iced.
While we've chosen a fun example here, the same logic applies to any set of tasks with dependencies, like building components in a large software project, performing data analysis in Map-Reduce job, or bringing up hardware components at boot time. (For example, the mother board has to initialize the hard drive before the BIOS tries to load the bootloader from disk.)
This process can be represented as a directed graph. Each step is a node, and we'll add directed edges between nodes to represent that one step has to be done before another.
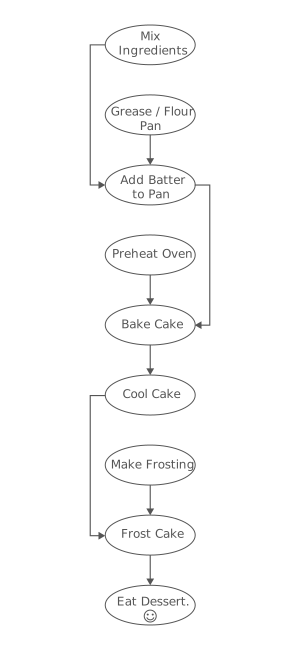
Once we have our dependencies represented using a directed graph, we can use topological sort to provide a valid ordering to tackle all the steps.
Topological Sort Interview Questions
Topological sort comes up in interviews whenever you see dependencies: prerequisites, build steps, or anything that has to happen "before" something else. A few classics:
-
Course schedule. Given a list of courses and their prerequisites, can you finish all of them? Make each course a node, and add an edge from each prerequisite to the course that requires it. You can finish everything exactly when the graph has no cycle—that is, when a topological sort includes every course. A common follow-up asks for an order to take the courses in. That's the topological ordering itself.
-
Build order. Given a list of projects and the projects each one depends on, find an order to build them so every project's dependencies get built first. Build tools and package managers solve this exact problem.
-
Alien dictionary. Given a list of words sorted in an unknown alphabet, figure out the order of the letters. Compare each pair of neighboring words: the first position where they differ tells you that one letter comes before another, so add an edge between those two letters. Then topologically sort the letters. (Watch out for invalid input, like "abc" listed before "ab"—a word can't come before its own prefix.)
-
Parallel scheduling. If you can take any number of courses at once, what's the fewest number of semesters you need? Run Kahn's algorithm in "waves," taking every node with an indegree of zero at once. The number of waves is your answer.
-
Shortest paths in a DAG. Go through the nodes in topological order, updating the best known distance to each node's neighbors as you go. That finds the shortest paths from a starting node in O(V + E) time—faster than Dijkstra's algorithm, and it works even when some edge weights are negative.
See also:
Interview coming up?
Get the free 7-day email crash course. You'll learn how to think algorithmically, so you can break down tricky coding interview questions.
No prior computer science training necessary—we'll get you up to speed quickly, skipping all the overly academic stuff.
No spam. One-click unsubscribe whenever.
You're in! Head over to your email inbox right now to read day one!